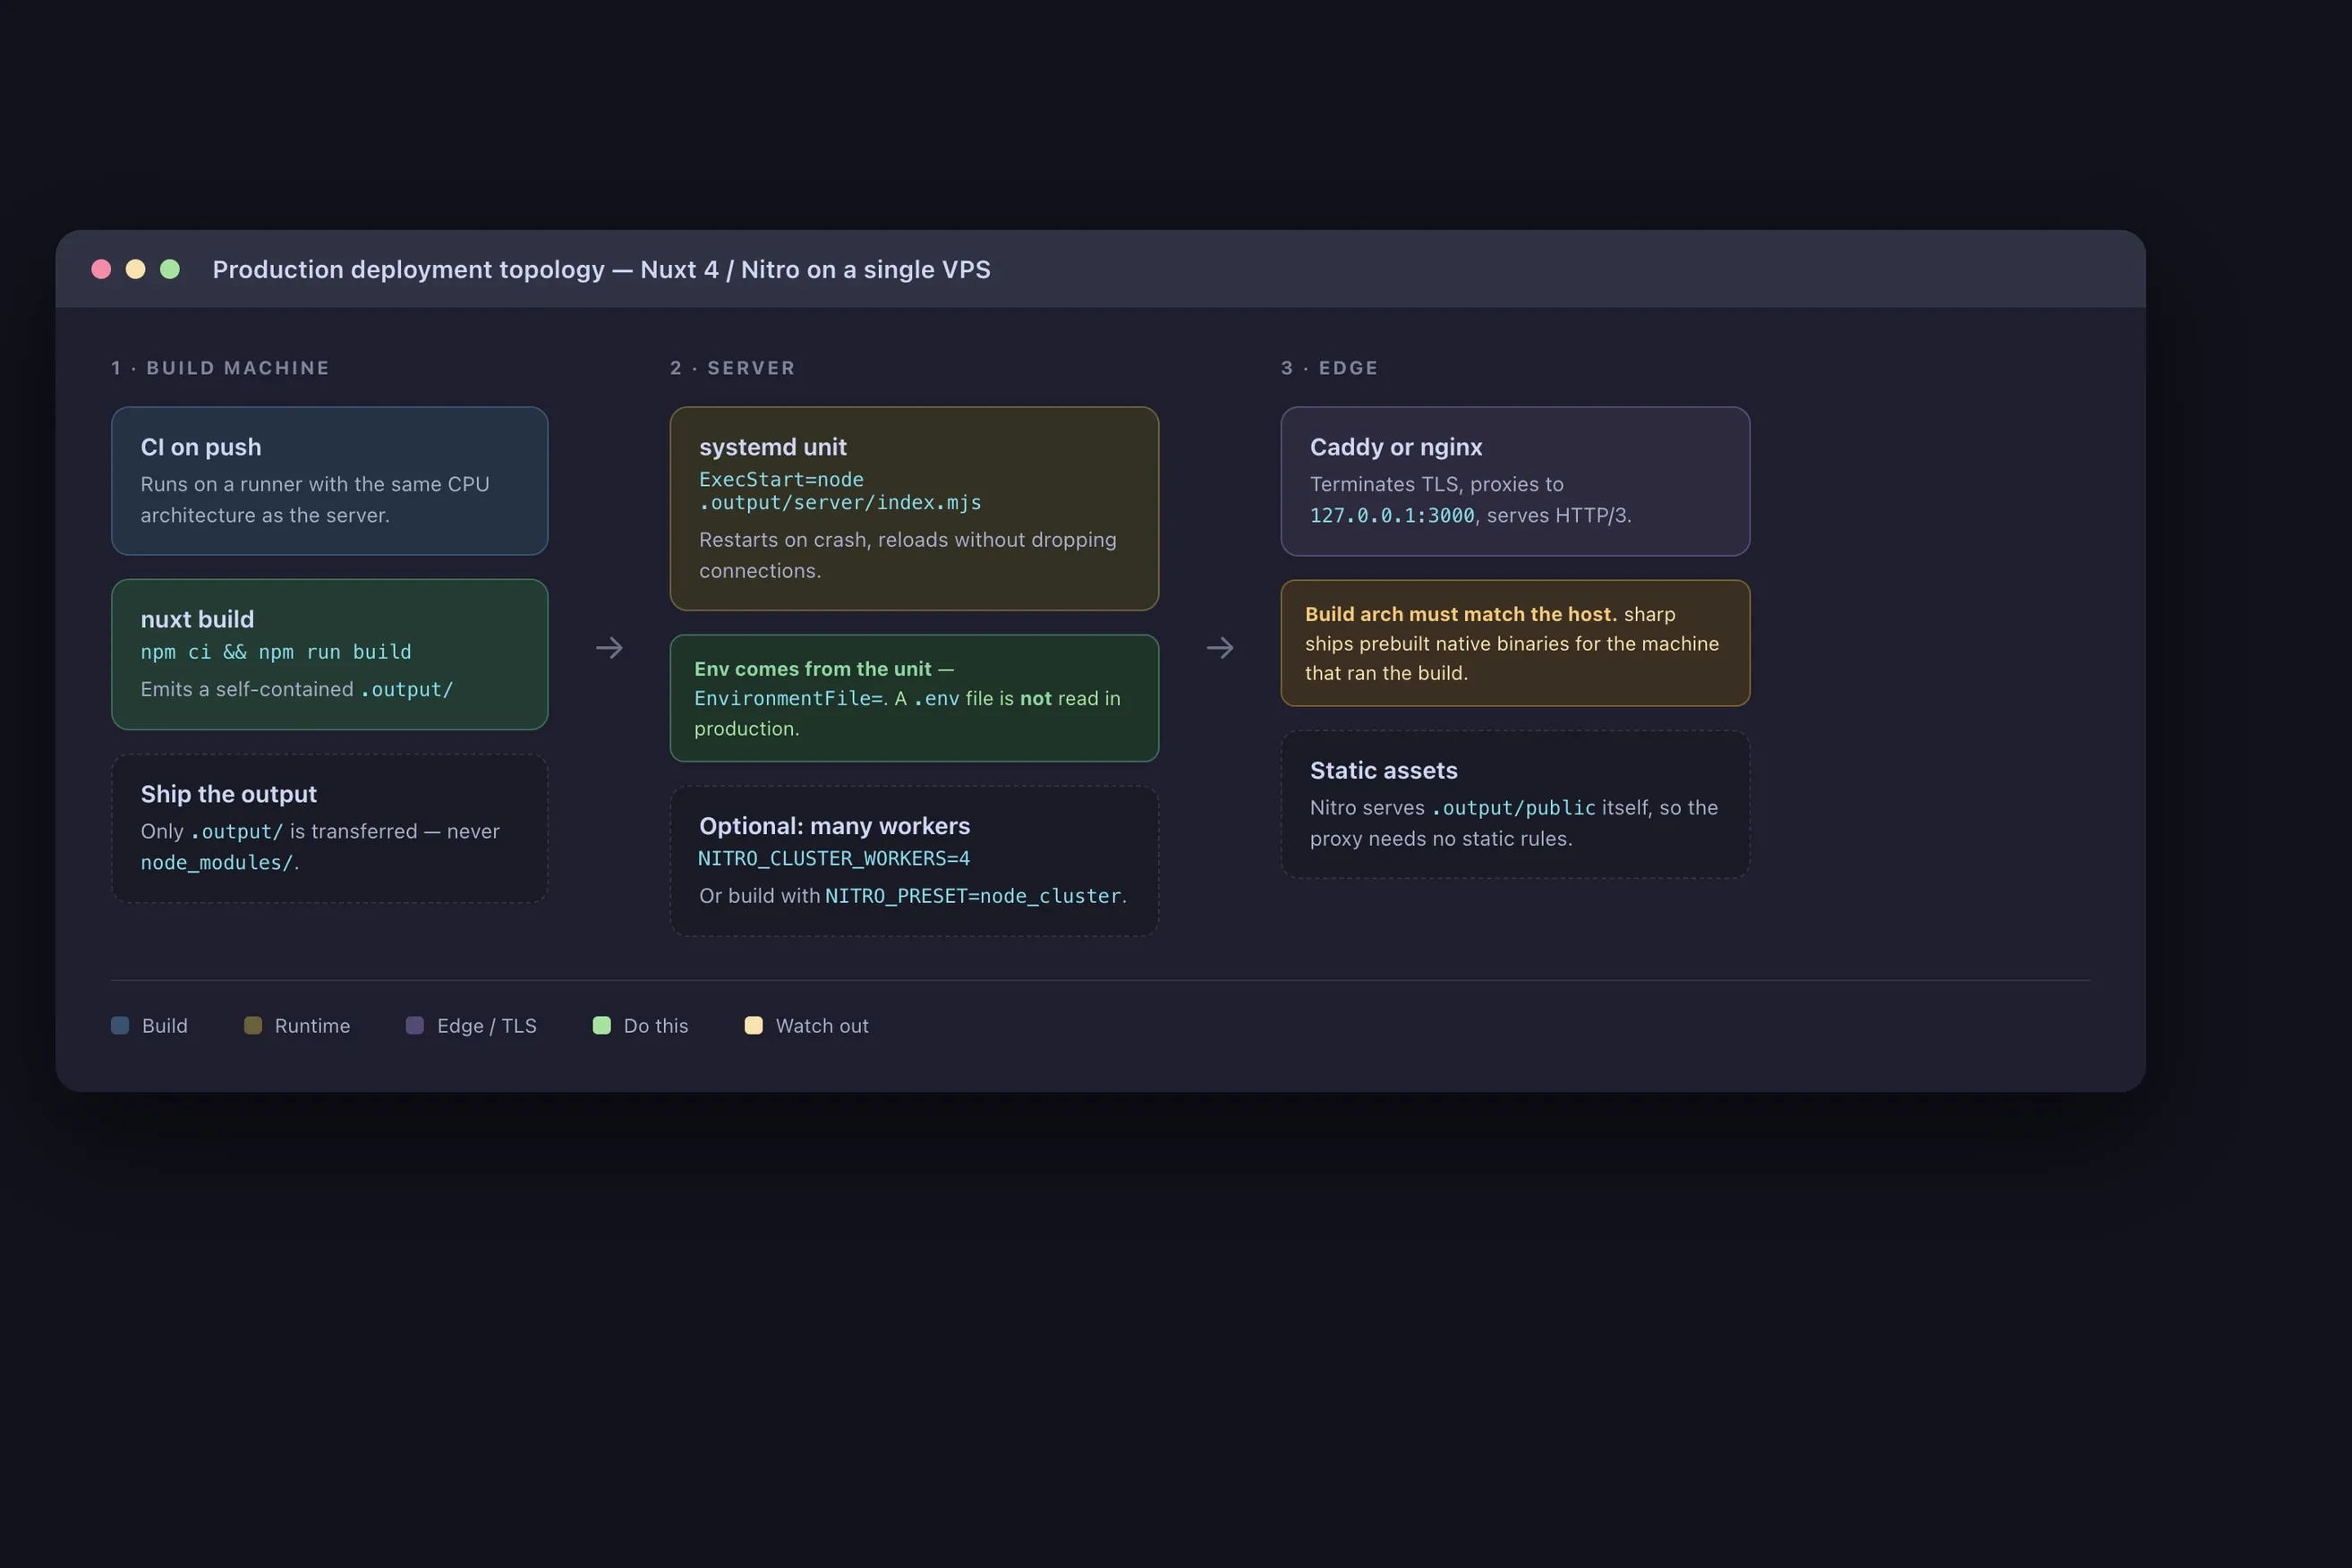
Deploy your Nuxt app to production
In 2020 I wrote a post on deploying a Nuxt app with PM2. A lot of it no longer applies. nuxt start does not exist any more, the config file is nuxt.config.ts instead of nuxt.config.js, and the build output is no longer something you serve with a hand-written process command — it is a self-contained server you run with one line. This post replaces it. If you landed here from a search, use this one and ignore anything about target: "server".
Everything below was verified against Nuxt 4.5.2 and Nitro 2.13.4 on Node 24, the current LTS line.
What the build actually produces
Start with a production build the way you always have.
npm ci
npm run build
The interesting part is the directory it leaves behind. Nuxt no longer hands you a dist/ folder to serve and a nuxt start command to run it. nuxt build produces .output/, and everything the server needs is inside it.
.output/
├── nitro.json      # preset, framework + engine versions, the preview command
├── public/          # hashed client assets, static files
└── server/
    ├── index.mjs    # the entrypoint — 491 bytes
    ├── chunks/      # server-rendered routes and runtime
    ├── node_modules/# 93 production dependencies, already bundled
    └── package.json
server/node_modules is the part people miss. Nitro does not expect you to run npm install on the server, because it has already resolved and vendored every production dependency into the output. You can copy this directory to a bare machine with nothing but Node installed and it will run.
nitro.json is a small manifest that records how the build was made:
{
  "date": "2026-09-28T13:46:15.494Z",
  "preset": "node-server",
  "framework": { "name": "nuxt", "version": "4.5.2" },
  "versions": { "nitro": "2.13.4" },
  "commands": { "preview": "node server/index.mjs" },
  "config": {}
}
Running it
One command. This is the whole production start procedure:
NODE_ENV=production node .output/server/index.mjsThe server listens on port 3000 and serves both the rendered HTML and the static assets in public/, so you do not need nginx to serve any files itself.
Keep NODE_ENV=production in there. The Nuxt docs call this out specifically: without it, Vue Router keeps its development warnings enabled and your logs fill with messages like [Vue Router warn]: No match found for location with path … for every unmatched route.
There is a nuxt preview command, and it is genuinely useful — but not for this. Its own output says so, and the wording is worth reading:
You are previewing a Nuxt app. In production, do not use this CLI.
Instead, run node server/index.mjs directly.
It exists to give you a .env-loaded, rebuilt-on-demand local environment. There is also no nuxt start command in Nuxt 4 any more — if a tutorial tells you to run it, that tutorial is at least five years out of date.
Environment variables
The server reads these directly:
NITRO_PORTorPORT— defaults to3000NITRO_HOSTorHOST— defaults to0.0.0.0NITRO_SSL_CERTandNITRO_SSL_KEY— set both and it serves HTTPS itself. Do not do this in production; terminate TLS at the proxy instead.
Anything in runtimeConfig can be overridden by prefixing the key with NUXT_ or NITRO_. The mapping is mechanical: camelCase becomes SNAKE_CASE, and nesting is joined with a single underscore.
runtimeConfig: {
  apiSecret: "...",              // NUXT_API_SECRET
  public: {
    siteUrl: "https://example.com" // NUXT_PUBLIC_SITE_URL
  }
}
This is worth internalising because a wrong name fails silently. Nothing warns you, runtimeConfig just keeps its build-time value and your app quietly talks to the wrong API.
The trap that catches everyone
A .env file is not read in production. nuxt preview loads it and says so; node .output/server/index.mjs does not, because by then there is no build tooling left to read it. This is not a Nuxt bug, it is the intended behaviour — but it means a .env that works perfectly in npm run dev and npm run preview will be silently absent the moment you deploy.
The usual failure is not a crash. It is a green deploy that returns empty content, because a missing project ID or API base silently produces an empty query result. So:
- Put production secrets in the environment your process manager provides, not in a
.envnext to the build. - Or bake non-secret values into the build with
NUXT_PUBLIC_*at build time. - After deploying,
curla real route and check the response body. A 200 with the wrong content is still a 200.
Keeping it running
systemd
On a single server, systemd is the supervisor. It is already running, it restarts on boot, and it needs no global install. Put a unit next to the build:
[Unit]
Description=Nuxt production server
After=network-online.target

[Service]
Type=simple
User=nuxt
WorkingDirectory=/srv/nuxt-app
Environment=NODE_ENV=production
EnvironmentFile=/etc/nuxt-app.env
ExecStart=/usr/bin/node .output/server/index.mjs
Restart=always
RestartSec=5

# Nitro drains in-flight requests on SIGTERM, which is systemd's default,
# and gives up after 30s. Give systemd a little more room than that.
KillSignal=SIGTERM
TimeoutStopSec=35

NoNewPrivileges=true
PrivateTmp=true
ProtectSystem=strict
ProtectHome=true

[Install]
WantedBy=multi-user.target
Then:
sudo systemctl daemon-reload
sudo systemctl enable --now nuxt-app
systemctl status nuxt-app
Three of those lines are doing real work, and two of them are the opposite of common advice:
- Do not set
KillSignal=SIGINT. The usual Node-on-systemd folklore says to, because plain Node exits abruptly onSIGTERM. Nitro does not — it trapsSIGTERM SIGINTby default, stops accepting connections, and waits for in-flight requests. systemd's defaultSIGTERMis already the right signal. RestartSecdefaults to 100ms, which turns a crash loop into a spin. Five seconds is a saner floor.TimeoutStopSecdefaults to 90s and Nitro's own shutdown timeout is 30s, so the defaults already line up. The explicit35only matters if you raiseNITRO_SHUTDOWN_TIMEOUTpast 30s — set that above 90 and systemd willSIGKILLthe process mid-drain.
You can retune Nitro's half of this with NITRO_SHUTDOWN_TIMEOUT, NITRO_SHUTDOWN_SIGNALS, NITRO_SHUTDOWN_DISABLED, and NITRO_SHUTDOWN_NO_FORCE_EXIT.
systemctl reload nuxt-app gives you a zero-downtime restart; journalctl -u nuxt-app -f follows the logs.
PM2
PM2 is not deprecated and I am not going to pretend otherwise — it is maintained, and Nuxt's own deployment docs still recommend it as the quick option. What has changed is the config. The old approach of pointing script at a Nuxt CLI binary and passing start as an argument is gone, because that binary and that subcommand are gone.
The current version Nuxt documents is a single process, no arguments, running the built entrypoint:
module.exports = {
  apps: [
    {
      name: 'nuxt-app',
      script: './.output/server/index.mjs',
      env: { NODE_ENV: 'production' },
    },
  ],
}
Two things to note. Use ecosystem.config.cjs, not .js — if your package.json has "type": "module", a CommonJS config will not load. And if you want PM2 to handle multiple workers, the ecosystem file can do it natively:
module.exports = {
  apps: [
    {
      name: 'nuxt-app',
      script: './.output/server/index.mjs',
      exec_mode: 'cluster',
      instances: 'max',
      env: { NODE_ENV: 'production' },
    },
  ],
}
One caution specific to PM2. Its pm2 deploy <config> <env> command — the git-push-over-SSH mechanism my 2020 post used — still exists and is still documented, but its documentation is visibly stale: the current PM2 docs still show "ref": "origin/master" as the example. If you are starting fresh, pushing a build artifact from CI is both simpler and easier to audit than letting a laptop SSH into production and run a build there.
Many workers without a supervisor
If you want more than one process and do not want a proxy doing the load balancing, Nitro has a cluster mode built in. Build with the node-cluster preset:
NITRO_PRESET=node_cluster npm run buildA master process forks workers and re-forks any that die. The count comes from NITRO_CLUSTER_WORKERS and defaults to your core count:
NITRO_CLUSTER_WORKERS=3 node .output/server/index.mjsThe preset name is node-cluster but the env var in the Nuxt docs is written node_cluster. Both work — Nitro normalises the name before looking it up — so do not be alarmed by the mismatch.
Presets, and the one that bites
The preset decides what shape the build takes. It is set in config, or per build via the environment:
export default defineNuxtConfig({
  nitro: { preset: 'node-server' },
})NITRO_PRESET=node-server npm run buildThere are around thirty — bun, deno, cloudflare, vercel, netlify, aws-lambda, static and so on. The one to know about is static, which switches Nitro into pre-render-only mode.
Be careful with typos here. Nitro normalises the name and, if nothing matches, quietly falls back to auto-detection rather than failing. A build with NITRO_PRESET=node-serve does not error — it produces a perfectly normal node-server build, and you find out at deploy time. The one case that does throw is a real preset name blocked by an older compatibilityDate, and the error message tells you exactly which date it needs.
TLS and the reverse proxy
Nitro can serve HTTPS itself, but you should not. Terminate at a proxy, proxy to the Node process over loopback, and let the proxy handle certificates and HTTP/2 or 3.
Caddy is the shortest path — automatic certificates, no renewal cron, no certbot:
example.com {
  reverse_proxy 127.0.0.1:3000
}
The nginx equivalent, if you already run it:
server {
  listen 443 ssl http2;
  server_name example.com;

  ssl_certificate     /etc/letsencrypt/live/example.com/fullchain.pem;
  ssl_certificate_key /etc/letsencrypt/live/example.com/privkey.pem;

  location / {
    proxy_pass http://127.0.0.1:3000;
    proxy_http_version 1.1;
    proxy_set_header Host              $host;
    proxy_set_header X-Real-IP         $remote_addr;
    proxy_set_header X-Forwarded-For   $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;
  }
}
The X-Forwarded-* headers matter. Without X-Forwarded-Proto, Nuxt cannot tell that the original request was HTTPS and will generate http:// URLs for assets and redirects on a site served over TLS.
Deploying without downtime
Build once, ship the output, swap a symlink. This keeps the old release serving traffic until the new one is verified, and makes a rollback a symlink change.
- Build in CI and archive
.output/. - Upload to a new timestamped release directory on the server.
- Point the
currentsymlink at it and reload the service.
# on the server
release=/srv/nuxt-app/releases/$(date +%s)
mkdir -p "$release"
tar -xzf .output.tar.gz -C "$release"
ln -sfn "$release" /srv/nuxt-app/current
systemctl reload nuxt-app
Keep the last few release directories. If the new build is serving errors, ln -sfn back to the previous one and reload.
Build on the same architecture you deploy to
This one has bitten me and it is worth its own section. If your app uses @nuxt/image, the build bakes in prebuilt sharp binaries for whichever machine ran it. Build on linux/amd64, deploy to an arm64 VPS, and image processing fails at runtime in a way that looks nothing like an architecture problem.
The build tells you, at the end, exactly what it bundled:
[@nuxt/image] i sharp binaries have been included in your build for darwin-arm64.
Make sure you deploy to the same architecture.
So read the build log. If CI runs on a different architecture from production, set it explicitly, or build inside the target architecture — a container image, or a runner matching the server.
A short checklist
- Build with
npm ci && npm run build; deploy only.output/. - Start it with
NODE_ENV=production node .output/server/index.mjs. - Secrets go in the process manager's environment, never a
.envin the release. - Use a supervisor — systemd, PM2, or a container runtime — so it restarts on crash and on reboot.
- Terminate TLS at a proxy and forward
X-Forwarded-Proto. - Check that the build architecture matches the server.
curla real route after deploying and read the body, not just the status code.
References
nuxt build — a self-contained .output/ directory